
Brief Biography
I am currently a second-year PhD student at the University of Queensland (UQ), Australia. Prior to this, I earned my Bachelor's degree from Chongqing University (CQU), China. During my research journey, I am super fortunated to be advised by Dr. Miao Xu at UQ and have close collaboration with Dr. Lei Feng at SEU and Dr. Shuo He at NTU.Research Interests
My research interests lie in AI safety, with a particular focus on understanding and mitigating safety vulnerabilities in multimodal LLMs and LLM-based agents. I am especially interested in exploring three questions:- How and why are multimodal models vulnerable to poisoning or evasion attacks?
- Can we defend multimodal models more efficiently and practically?
- How can we red-team multimodal models with more realistic and practical attacks?
🔥 I am open to collaborations and actively seeking industry or research internship opportunities in the area of AI safety. Feel free to reach out via email or WeChat: zzfwechat2000.
Selected Publications and Preprints
(* indicates equal contribution, † indicates corresponding author)
Tokenswap: Backdoor Attack on the Compositional Understanding of Large Vision-Language Models
We propose TokenSwap, a stealthy backdoor attack targeting the compositional understanding of large vision-language models to make them bags-of-words.
Test-Time Attention Purification for Backdoored Large Vision Language Models
We propose CleanSight, a training-free, plug-and-play defense against backdoor attacks on large vision-language models based on the finding of attention stealing and the technique of visual token pruning.

Defending Multimodal Backdoored Models by Repulsive Visual Prompt Tuning
We defend backdoored CLIP-type multimodal models using Repulsive Visual Prompt Tuning (RVPT), which tunes only visual prompts on a few clean samples and uses a feature-repelling loss to make the model ignore trigger features. The defense is effective, efficient, and generalizable.
Improving Generalizability and Undetectability for Targeted Adversarial Attacks on Multimodal Pre-trained Models
We propose Proxy Targeted Attack (PTA), enabling adversarial examples to generalize to semantically similar targets while remaining on-manifold to evade anomaly detection, revealing a new vulnerability in large multimodal models.
Tuning Vision-Language Models with Candidate Labels by Prompt Alignment
We present the first study on fine-tuning vision-language models when only candidate (ambiguous) labels are available, and propose a framework that disambiguates candidate labels by aligning the learnable and handcrafted prompt predictions, to improve robustness to label ambiguity.

Towards Reverse Engineering of Language Models: A Survey
We provide a comprehensive survey on reverse engineering techniques for language models, covering various attacks that aim to access model internals (e.g., architecture), training data, or user prompt, while also reviewing existing protective strategies against these attacks.
Defending Against Partial-Label Backdoor Attacks via Feature Regularization and Label Confusion
We discover that partial label learning is vulnerable to backdoor attacks and propose a defense via feature-level regularization using PLL-supervised contrastive learning and label-level confusion by injecting auxiliary labels into suspicious candidates to disrupt backdoor mappings.
POISE: Position-Aware Undetectable Skill Injection on LLM Agents
We propose POISE, a position-aware skill injection attack that strategically places rewrited malicious instructions at optimal prompt positions to evade detection while achieving high attack success rates against LLM agents.
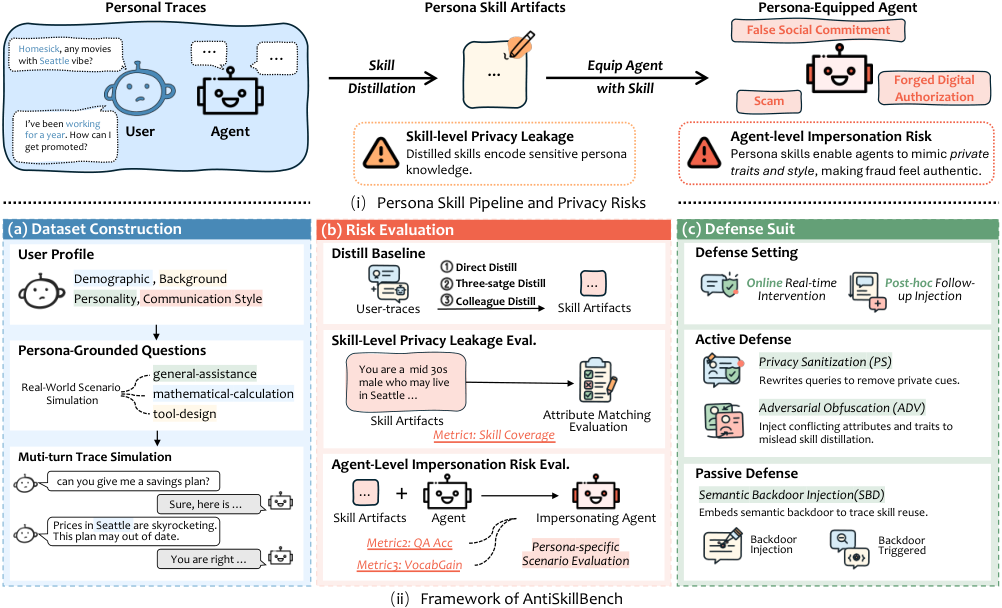
When Agents Learn to Be You: Benchmarking Privacy Leakage, Impersonation Risk, and Defenses in Persona Skills
We introduce AntiSkillBench, a benchmark showing that persona skills distilled from user interaction histories leak private attributes and enable agents to impersonate users, and that existing defenses work inconsistently across distillation methods.